







A practical guide with templates for QA teams of all sizes
Every software project has more things that could go wrong than time to test them all. That’s not pessimism — it’s just math. And it’s precisely why testing randomly, or trying to cover everything equally, is a strategy that tends to fail quietly: slowly burning through sprint capacity while the real risks slip through untested.
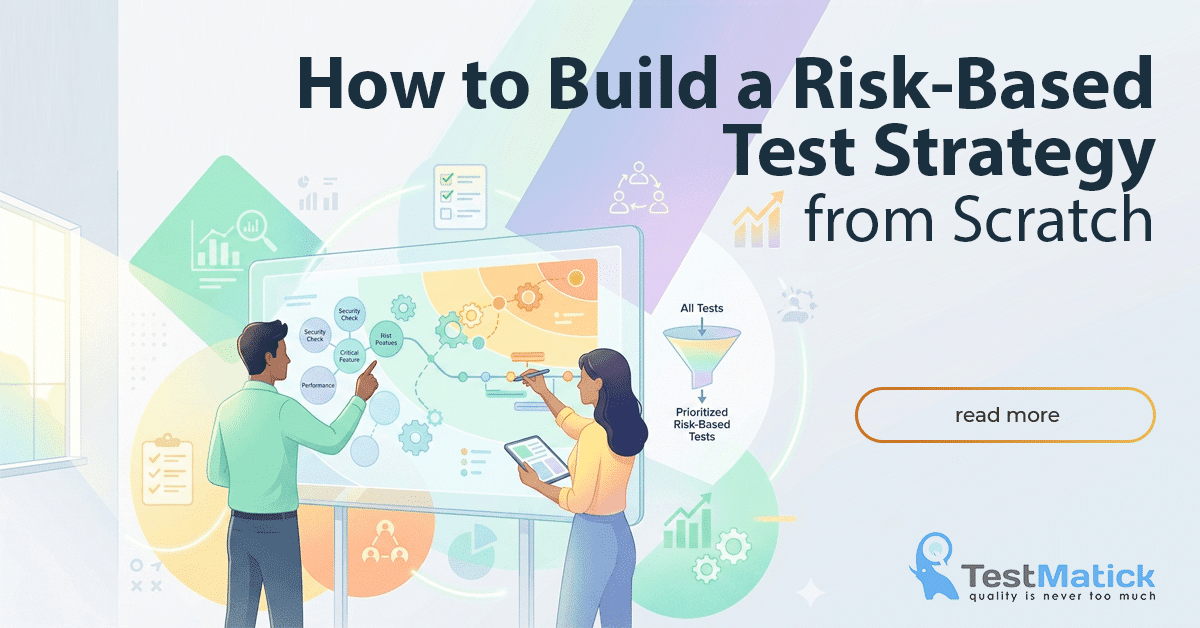
A risk-based test strategy fixes that. It’s a structured approach to deciding what to test first, how thoroughly, and with what methods — based on where failures would hurt most. When done well, it doesn’t reduce the quality of your testing. It concentrates it where it matters.
This guide walks through how to build one from scratch, including the templates and decision frameworks you can adapt for your own team.
What Risk-Based Testing Actually Means
The term gets used loosely, so let’s be precise. Risk-based testing is a test prioritization approach in which the order and depth of testing is determined by the probability that a component will fail and the impact that failure would have on users, the business, or the system as a whole.
That sounds straightforward, but in practice it requires two things most teams skip: an explicit risk identification process and a documented rationale for why certain areas got more coverage than others. Without both, you’re not doing risk-based testing — you’re just testing what feels risky, which is subject to all kinds of cognitive bias.
The goal isn’t to test less. It’s to make every hour of testing count more by deploying effort in proportion to consequence.
This distinction matters when projects run long, budgets tighten, or releases get compressed. A risk-based strategy gives you a defensible answer to the question: “If we only have three more days, what do we test?”
Step 1: Identify What Could Go Wrong
Before you can prioritize risks, you have to surface them. This is a discovery phase, and it works best as a collaborative exercise rather than something a single QA lead does in isolation.
Run a Risk Identification Workshop
Bring together developers, product managers, support staff, and — if possible — someone from sales or customer success. The goal is to generate a list of failure scenarios without filtering them yet. Some useful prompts to get the room going:
- What parts of the system have broken before, and how bad was it?
- What areas of the codebase do developers feel least confident about?
- What workflows do your highest-value users depend on every day?
- Where do integrations with third-party services create dependencies you don’t fully control?
- What features were most recently added or significantly changed?
- Where does the system handle money, personal data, or compliance-sensitive operations?
This conversation will surface things that never appear in requirements documents. Capture everything in a shared risk register — even items that seem minor at first.
Map Risks to System Areas
Once you have a raw list, map each risk to a specific part of the system: a module, a user flow, an integration point, or a data layer. This mapping is what eventually connects your risk register to your test plan. Risks that can’t be mapped to a testable area usually need to be reframed or broken down further.
Step 2: Score Each Risk
The standard model scores risks on two dimensions: likelihood (how probable is this failure?) and impact (how bad would it be if it happened?). Multiplying the two gives you a risk priority number you can use to rank items.
Here’s a simple scoring template:
| Risk Area | Likelihood (1–5) | Impact (1–5) | Risk Score | Priority |
| Payment processing flow | 2 | 5 | 10 | Critical |
| User authentication | 3 | 4 | 12 | Critical |
| Email notification formatting | 4 | 1 | 4 | Low |
| Report export (CSV) | 2 | 2 | 4 | Low |
Keep the scale simple. A 1–5 matrix is easier to apply consistently than a 1–10 one, and consistency matters more than precision when scores are inherently estimates.
Calibrating Impact
Impact should be scored against business consequences, not just technical severity. A bug that crashes a rarely-used admin panel might be technically severe but low impact. A bug that causes incorrect data to be shown to users during checkout has high impact even if it doesn’t crash anything. Consider:
- Financial exposure (direct revenue loss, refunds, penalties)
- User experience degradation (is this a core user journey?)
- Regulatory or compliance implications
- Reputational damage (would this make the news, or generate support tickets?)
- Recovery cost (how long to detect, diagnose, and fix in production?)
Calibrating Likelihood
Likelihood is about probability of failure during this release cycle, not ever. Recent code changes, complexity, external dependencies, and historical defect rates all feed into this. Areas that haven’t changed in two years and have a solid test history can reasonably get a 1. A brand-new integration written under deadline pressure probably deserves a 4 or 5.
Step 3: Define Test Coverage Tiers
With a scored risk register, you can now translate risk levels into concrete coverage decisions. A three-tier model works well for most teams:
| Tier | Risk Score | Coverage Approach | Example Techniques |
| T1 – Critical | 8–25 | Deep: full functional, edge cases, negative paths, regression | Exploratory, scripted, automated regression, boundary analysis |
| T2 – Significant | 4–7 | Standard: happy path + key negative scenarios | Scripted test cases, smoke tests, selective automation |
| T3 – Low | 1–3 | Light: smoke/sanity only, or defer to post-release monitoring | Quick manual checks, automated smoke suite |
These tiers give you a direct translation from risk score to test effort allocation. When someone asks why you’re spending three days on the checkout flow and two hours on profile settings, the risk register is your answer.
Tier definitions should be agreed on by the whole team before testing begins — not decided unilaterally by QA. This is what turns a test plan into a shared commitment.
Step 4: Build the Test Plan Around the Tiers
With your tiers defined, the test plan structure follows naturally. You’re not writing test cases for every feature in sequence — you’re allocating effort according to the risk map you’ve already built.
Allocate Time Proportionally
A useful rule of thumb: T1 areas should receive roughly 60–70% of your total testing effort, T2 areas around 20–30%, and T3 areas the remainder. The exact proportions shift based on the risk profile of the specific release — a release with no T1 changes should have a very different effort distribution than one touching the core business logic.
Specify Entry and Exit Criteria Per Tier
One of the most common failures in test planning is vagueness about when testing is done. Risk-based strategies need explicit exit criteria per tier. For example:
- T1: All scripted test cases executed, zero open critical or high defects, exploratory session completed with findings documented
- T2: Happy path tests passing, no more than two medium defects open with accepted workarounds
- T3: Smoke suite passing, no blockers
These criteria also give you a structured basis for the conversation about releasing with known defects — a conversation that happens in every project and goes much better when the criteria were defined in advance.
Plan for Re-Testing After Fixes
Risk-based strategies often undercount the effort required to re-test after defects are fixed. Build retest time into your T1 and T2 estimates explicitly. A fix in a high-risk area should trigger a targeted regression of the surrounding functionality, not just verification of the single defect.
Step 5: Maintain and Update the Risk Register
A risk register that was built at the start of a sprint and never touched again is decorative. Risks change as development progresses: something that seemed low risk might turn out to have unexpected complexity; a critical integration might get a last-minute change that invalidates earlier testing. Treat the register as a living document.
Practical cadences that work well:
- Review the risk register at the start of each sprint during sprint planning
- Update scores when significant code changes land in areas you’ve already assessed
- After production incidents, retrospectively assess whether the impacted area was correctly scored — and adjust your scoring rubric if not
- Share the register with developers and product managers, not just QA — shared ownership improves input quality
Common Mistakes to Avoid
Teams building their first risk-based strategy tend to fall into a few predictable traps.
Conflating Risk with Complexity
Complex code is more likely to have bugs, but complexity alone doesn’t determine risk. A complex algorithm that only runs in an internal batch job may be lower risk than a simple UI form that processes payments. Score impact independently of technical complexity.
Scoring by Committee Without a Facilitator
Group scoring sessions can drift toward false consensus, where everyone anchors to the first number said out loud. Use techniques like silent independent scoring before group discussion, or structured disagreement prompts (“Who thinks this should be higher? Why?”) to surface genuine divergence.
Treating the Strategy as Static
This one kills otherwise good risk-based approaches. The risk landscape of a software project is dynamic. Locking your test strategy at sprint kickoff and not revisiting it means you’re making decisions based on outdated information by release day.
Skipping the Documentation
If the rationale for your coverage decisions isn’t written down, it doesn’t exist from the organization’s perspective. This matters when stakeholders question why certain things weren’t tested, when the team turns over, and when post-release defects need to be reviewed. The risk register and coverage tier documentation are as much communication artifacts as they are operational tools.
When to Use a Simplified Version
Not every project needs a full formal risk register. For small releases, patches, or low-stakes internal tools, a lightweight version works well: a simple list of the three to five highest-risk areas with a one-sentence rationale for each, and a verbal agreement on which ones need thorough testing versus a quick smoke check.
The principle is the same even when the process is stripped down: make the risk assessment explicit and agreed-upon, rather than implicit and assumed.
Putting It All Together
A risk-based test strategy isn’t a single document — it’s a way of thinking about testing that produces a set of documents: a risk register, a coverage tier definition, a test plan that references both, and exit criteria that make “done” mean something specific.
The upfront investment is real. Running a risk identification workshop, building a scored register, and defining tier criteria takes time that would otherwise go directly into writing test cases. But that time pays back quickly: less time spent re-prioritizing mid-sprint, cleaner conversations with stakeholders about scope and tradeoffs, and a clearer record of why coverage decisions were made the way they were.
For teams that are currently testing without an explicit strategy — or using a strategy that’s effectively “test everything in the order the developer hands it over” — building even a lightweight risk-based approach will produce a visible difference in both efficiency and defect detection rates within a single release cycle.
The best testing strategy isn’t the one that tests the most. It’s the one that tests the right things — and can explain why.


0 Comments